
Tests whether samples in the same group are more similar to each other
than to samples in other groups, from the ranks of the distances between
them. Gives the same \(R\) statistic and p-value as vegan::anosim().
Computes them in parallel C, from one ranking of the distances, without
the \(n \times n\) matrices that anosim() builds.
Usage
anosim(
  dm,
  groups,
  data = NULL,
  pairwise = FALSE,
  p_adjust = "holm",
  permutations = 999L,
  strata = NULL,
  seed = 0L,
  cpus = n_cpus()
)
Arguments
- dm
A
distobject, such as frombeta_div()orbray(), or a symmetric numeric matrix of distances. Must not containNAs or negative values.- groups
Each sample's group: a vector or factor with one value per sample, matched to the samples in
dmby name when both are named, else in the same order asdm. Or, whendatais given, the name of one of its columns (or a vector with one value per row ofdata). Values are treated as categories, even if they are numbers.- data
Optional sample metadata: a data frame with one row per sample, holding
groups(andstrata) as columns. Rows are matched to the samples indmby row name, and rows for other samples are ignored; without row names, they must be in the same order asdm. Default:NULL.- pairwise
Also test each pair of groups: run the same test on just the two groups' samples, for every pair, and adjust the pairs' p-values for multiple testing with
p_adjust. See Pairwise comparisons. Default:FALSE.- p_adjust
With
pairwise = TRUE, how to adjust the pairs' p-values for multiple testing: one ofstats::p.adjust.methods('holm','hochberg','hommel','bonferroni','BH','BY','fdr', or'none'), matched asstats::p.adjust()matches them. Giving it withoutpairwise = TRUEis an error. Default:'holm'.- permutations
The number of permutations. Default:
999. Alternatively, a matrix with one permutation of1:nper row, as frompermute::shuffleSet(), to use instead of random ones.- strata
Permute samples only within these groups (blocks), for designs such as repeated measures. With
data, the name of one of its columns, or a vector with one value per row ofdata. Withoutdata, a vector with one value per sample, matched to the samples by name when it has names, otherwise in the same order. Default:NULL(free permutation).- seed
An integer seed for the random permutations. The same seed gives the same p-value. Default:
0- cpus
How many parallel processing threads should be used. The default,
n_cpus(), is the CPU cores this R process may use, within any limits set on it. Results are the same for anycpus.
Value
A list of class c("ecodive_anosim", "ecodive_test"), the same
shape as the results of ecodive's other permutation tests, with:
statistic: The ANOSIM statistic,c(R = ...):vegan::anosim()'sstatistic.p_value: Permutation p-value,anosim()'ssignif.NAwithout permutations.z: How many standard deviations \(R\) lies above the mean of the permuted statistics: \((R - mean(R_{perm})) / sd(R_{perm})\), assummary(vegan::permustats()).NAwith fewer than two permutations, or when they are all equal.n_perm: The number of permutations.ranks: A data frame with one row for the pairs of samples in different groups ("Between") and one for each group, with the number ofpairsand theirmean_rank: the averages behindsummary(anosim(...))'s quantiles. A group of one sample has no pairs and anNAmean rank.pairwise: Withpairwise = TRUE, a data frame with one row per pair of groups, named like"a-b", and columnsR,z,n(the pair's samples),n_perm,p_value, andp_adjusted. See Pairwise comparisons. OtherwiseNULL.p_adjust: Withpairwise = TRUE, thep_adjustmethod used. OtherwiseNULL.permutation: How samples were permuted:"free","within strata", or"supplied matrix".
Attribute r_perm is a vector of the \(R\) statistics of each
permutation, anosim()'s perm.
Details
Method
ANOSIM (Clarke 1993) ranks all \(M = n(n-1)/2\) distances, from 1 for the smallest to \(M\) for the largest, giving tied distances the average of their ranks. With \(\bar{r}_B\) the mean rank of the distances between samples in different groups, and \(\bar{r}_W\) that of the distances within groups, $$R = \frac{\bar{r}_B - \bar{r}_W}{M / 2}$$ \(R\) is near 0 when the grouping explains nothing, and 1 when every distance within groups is smaller than every distance between them. Negative values mean samples are more alike between groups than within them.
For each permutation, the samples' group labels are shuffled and
\(R\) is recomputed. The p-value is the proportion of permutations,
counting the observed one, with an \(R\) at least as large:
\((1 + \#\{R_{perm} \ge R\}) / (1 + permutations)\). As in anosim(),
permuted statistics within sqrt(.Machine$double.eps) of the observed one
count as ties.
ANOSIM tests for differences in location, but is also sensitive to
differences in spread (dispersion) between groups (Warton et al. 2012);
see also permanova().
Speed and memory
The distances are ranked once, with a radix sort. Shuffling the labels doesn't change how many pairs are within groups, nor the sum of all the ranks, so each permutation needs only the sum of the ranks within groups: one pass over the ranks, shared by many permutations at once, with no \(n \times n\) matrix. Permutations run in parallel.
Reproducibility
The permutations come from seed, not from R's random number generator,
so set.seed() has no effect, and each permutation has a random number
stream of its own. P-values are identical from run to run and for any
number of cpus. The random permutations differ from anosim()'s, so
p-values agree with it only up to sampling error, unless the same
permutations matrix is given to both.
Differences from vegan::anosim()
anosim()here takes distances, not a community table: compute them first withbeta_div()or a metric function such asbray().The fields are named as in ecodive's other tests:
statisticis namedR,signifisp_value, and the permuted statistics are attributer_perm. The full vectors of ranks and their classes (dis.rankandclass.vec), each as long asdm, are summarized as the mean rank of each class, in fieldranks.stratapermutes freely within strata. For other restricted designs, pass apermutationsmatrix frompermute::shuffleSet().When there are fewer possible permutations than requested,
vegan(viapermute) runs each of them once instead.anosim()always draws random permutations.Negative distances are an error, where
veganwarns.
Pairwise comparisons
With pairwise = TRUE, each pair of groups is also tested on its own,
as q2-diversity's beta_group_significance(pairwise=True) does: the
distances are cut down to the two groups' samples, and the same test is
run on them, with the same number of permutations, the same strata
(cut down too), and the test's other arguments. The overall test is
unchanged.
Permutations: Each pair has random permutations of its own, drawn from
seedand the pair's position in the table, never from the number ofcpus. So a pair's p-value is reproducible, but differs (by sampling error) from that of the same test run by hand on the pair's samples with the sameseed. A suppliedpermutationsmatrix is cut down to each pair's samples by following each permutation's cycles: each of the pair's samples goes to the next of the pair's samples on its cycle. That gives a permutation of the pair's samples, uniformly distributed when the full one is, which keeps any restriction the matrix has, such as permuting only within strata.Multiple testing: The pairs' permutation p-values are adjusted together with
stats::p.adjust(method = p_adjust). The default, Holm's method, controls the family-wise error rate whatever the dependence between the pairs' tests.'BH'controls the false discovery rate instead, as q2-diversity's q-values do. The raw p-values are kept as well.Pairs that can't be tested: A pair the test can't be run on, such as two groups of one sample each, gets
NAs, with a warning, rather than an error. A test's other warnings for a pair, such as all of its distances being 0, are passed on, naming the pair.
The pairwise field of the result is a data frame with one row per pair
of groups, named like "a-b", in the order of the groups' factor levels
(sorted values, for other vectors). Its columns are the test's
statistics for the pair, z, n (the pair's number of samples),
n_perm, p_value (unadjusted) and p_adjusted. The p_adjust field
names the method, and print() shows both.
References
Clarke, K. R. (1993). Non-parametric multivariate analyses of changes in community structure. Australian Journal of Ecology, 18(1), 117-143. doi:10.1111/j.1442-9993.1993.tb00438.x
Warton, D. I., Wright, S. T., & Wang, Y. (2012). Distance-based multivariate analyses confound location and dispersion effects. Methods in Ecology and Evolution, 3(1), 89-101. doi:10.1111/j.2041-210X.2011.00127.x
Examples
# 30 samples in three treatment groups. The 'high' group has more
# of the first five genera.
set.seed(1)
counts <- matrix(rpois(30 * 20, 5), 30, 20)
rownames(counts) <- paste0('S', 1:30)
meta <- data.frame(
row.names = rownames(counts),
treatment = rep(c('ctrl', 'low', 'high'), each = 10),
site = rep(c('A', 'B'), 15) )
high <- meta$treatment == 'high'
counts[high, 1:5] <- counts[high, 1:5] + 5
dm <- bray(counts)
# Are samples more alike within treatment groups than between them?
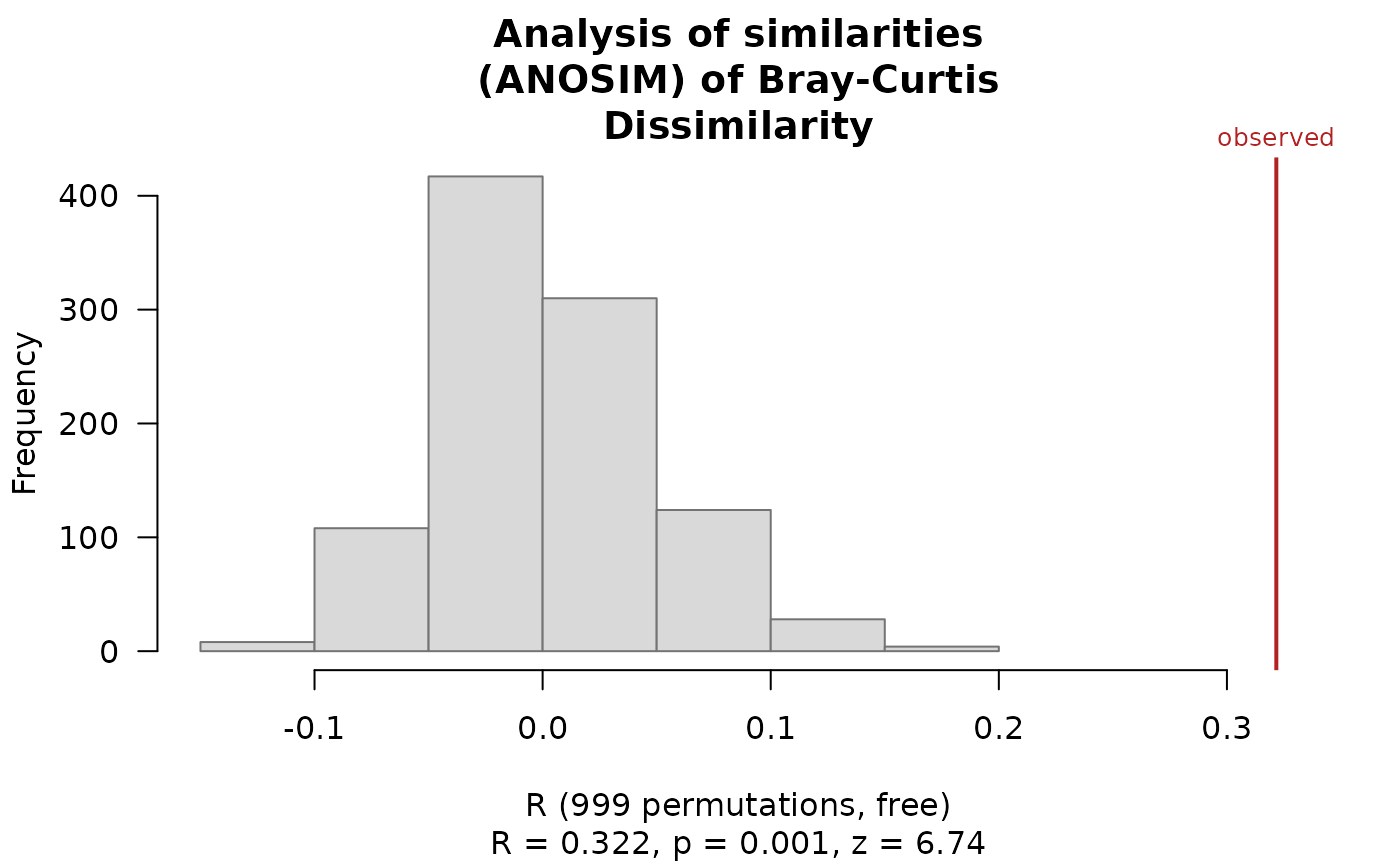
res <- anosim(dm, 'treatment', meta)
res
#> Analysis of similarities (ANOSIM) of Bray-Curtis Dissimilarity
#>
#> R = 0.3217, p = 0.001, z = 6.742
#> Permutations: 999 (free)
#>
#> Mean rank of the distances, between and within groups:
#> pairs mean_rank
#> Between 300 239.712
#> ctrl 45 221.111
#> high 45 43.500
#> low 45 244.644
plot(res)
 # The same, with the groups as a vector.
anosim(dm, meta$treatment)
#> Analysis of similarities (ANOSIM) of Bray-Curtis Dissimilarity
#>
#> R = 0.3217, p = 0.001, z = 6.742
#> Permutations: 999 (free)
#>
#> Mean rank of the distances, between and within groups:
#> pairs mean_rank
#> Between 300 239.712
#> ctrl 45 221.111
#> high 45 43.500
#> low 45 244.644
# Permuting treatment labels only within each site.
anosim(dm, 'treatment', meta, strata = 'site')
#> Analysis of similarities (ANOSIM) of Bray-Curtis Dissimilarity
#>
#> R = 0.3217, p = 0.001, z = 6.714
#> Permutations: 999 (within strata)
#>
#> Mean rank of the distances, between and within groups:
#> pairs mean_rank
#> Between 300 239.712
#> ctrl 45 221.111
#> high 45 43.500
#> low 45 244.644
# Mean rank of the distances between and within groups.
anosim(dm, 'treatment', meta)$ranks
#> pairs mean_rank
#> Between 300 239.7117
#> ctrl 45 221.1111
#> high 45 43.5000
#> low 45 244.6444
# Each pair of treatments, with Holm-adjusted p-values.
anosim(dm, 'treatment', meta, pairwise = TRUE)$pairwise
#> R z n n_perm p_value p_adjusted
#> ctrl-high 0.56455556 8.928828 20 999 0.001 0.003
#> ctrl-low -0.08133333 -1.223469 20 999 0.889 0.889
#> high-low 0.45800000 7.884991 20 999 0.001 0.003