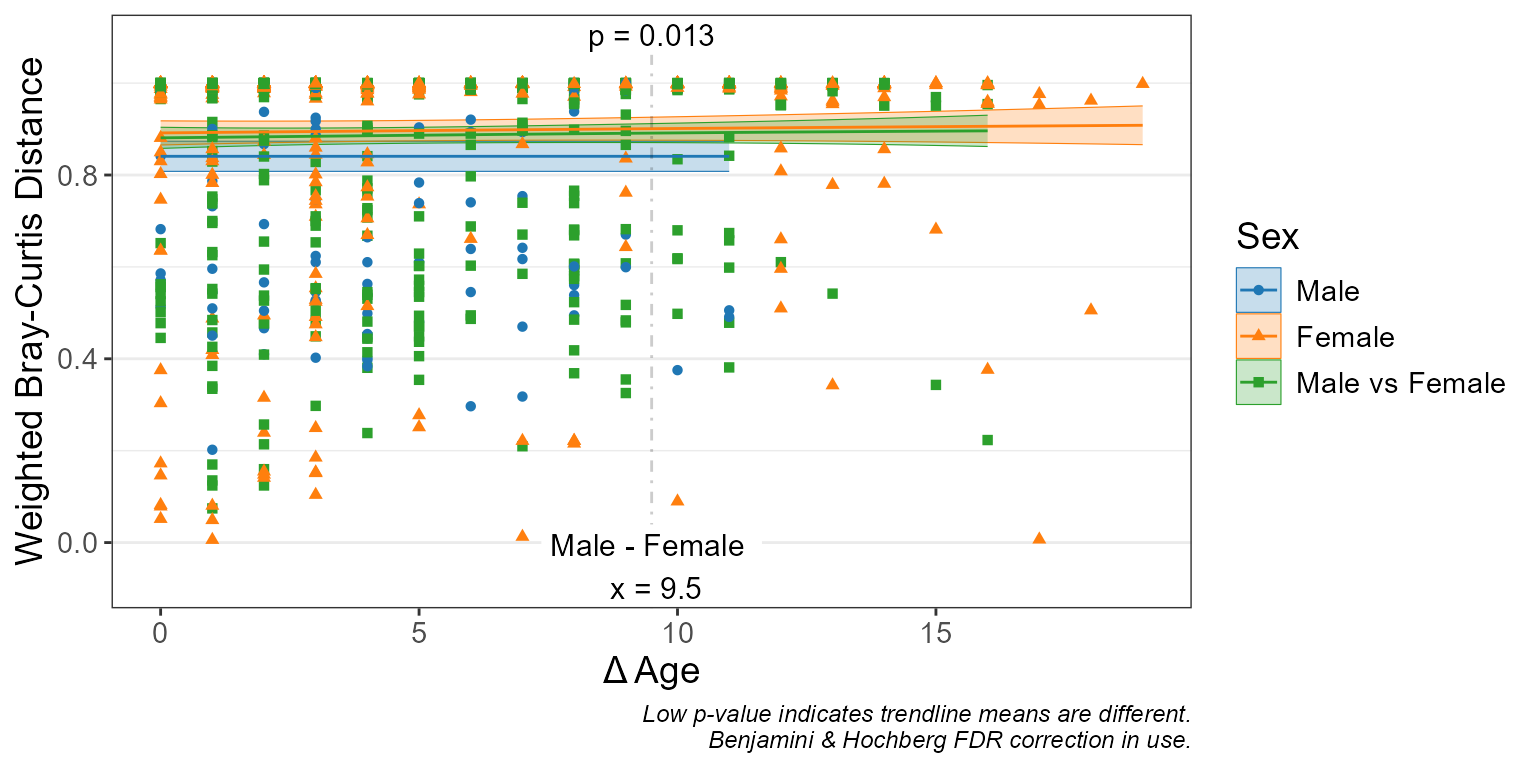
Visualize beta diversity with scatterplots and trendlines.
Usage
bdiv_corrplot(
  biom,
  x,
  bdiv = "bray",
  layers = "tc",
  weighted = NULL,
  tree = NULL,
  within = NULL,
  between = NULL,
  stat.by = NULL,
  facet.by = NULL,
  colors = TRUE,
  shapes = TRUE,
  test = "mantel",
  fit = "gam",
  at = NULL,
  level = 0.95,
  p.adj = "fdr",
  transform = "none",
  ties = "random",
  seed = 0,
  permutations = 999,
  alt = "!=",
  mu = 0,
  strata = NULL,
  caption = TRUE,
  check = FALSE,
  alpha = 0.5,
  cpus = n_cpus(),
  ...
)
Arguments
- biom
An rbiom object, or any value accepted by
as_rbiom().- x
Dataset field with the x-axis values. Equivalent to the
regrargument instats_table(). Required.- bdiv
Beta diversity distance algorithm(s) to use. Options are:
c("aitchison", "bhattacharyya", "bray", "canberra", "chebyshev", "chord", "clark", "sorensen", "divergence", "euclidean", "generalized_unifrac", "gower", "hamming", "hellinger", "horn", "jaccard", "jensen", "jsd", "lorentzian", "manhattan", "matusita", "minkowski", "morisita", "motyka", "normalized_unifrac", "ochiai", "psym_chisq", "soergel", "squared_chisq", "squared_chord", "squared_euclidean", "topsoe", "unweighted_unifrac", "variance_adjusted_unifrac", "wave_hedges", "weighted_unifrac"). For the UniFrac family, a phylogenetic tree must be present inbiomor explicitly provided viatree=. Supports partial matching. Multiple values are allowed for functions which return a table or plot. Default:"bray"- layers
The elements to draw, such as the trend line, its confidence band, and the points. One or more of
c("trend", "confidence", "point", "name", "residual"). Single letter abbreviations are also accepted. For instance,c("trend", "point")is equivalent toc("t", "p")and"tp". Default:"tc"- weighted
(Deprecated - weighting is now inherent in bdiv metric name.) Take relative abundances into account. When
weighted=FALSE, only presence/absence is considered. Multiple values allowed. Default:NULL- tree
A
phyloobject representing the phylogenetic relationships of the taxa inbiom. Only required when computing UniFrac distances. Default:biom$tree- within, between
Dataset field(s) for intra- or inter- sample comparisons. Alternatively, dataset field names given elsewhere can be prefixed with
'=='or'!='to assign them towithinorbetween, respectively. Default:NULL- stat.by
Dataset field with the statistical groups. Must be categorical. Default:
NULL- facet.by
Dataset field(s) to use for faceting. Must be categorical. Default:
NULL- colors
How to color the groups. Options are:
TRUE-Automatically select colorblind-friendly colors.
FALSEorNULL-Don't use colors.
- a palette name -
Auto-select colors from this set. E.g.
"okabe"- character vector -
Custom colors to use. E.g.
c("red", "#00FF00")- named character vector -
Explicit mapping. E.g.
c(Male = "blue", Female = "red")
A named vector doesn't have to match the plotted groups exactly. Names for groups that aren't in the plot (for instance, after filtering samples) are ignored, and groups without a name get default colors that aren't already in use. Any unnamed entries in the vector are used for those groups first, in order. A warning is given only when a name isn't recognized and a group was left without one, as a misspelled name would do. Names can be case-insensitive abbreviations (
c(m = "blue", f = "red")). For between-group beta diversity, a pair is named as its label shows it, e.g.c("Female vs Male" = "purple"). See "Aesthetics" section below for additional information. Default:TRUE- shapes
Shapes for each group. Options are similar to
colors's:TRUE,FALSE,NULL, shape names (typically integers 0 - 17), or a named vector mapping groups to specific shape names. As withcolors, names for groups that aren't in the plot are ignored and groups without a name get default shapes. See "Aesthetics" section below for additional information. Default:TRUE- test
Method for computing p-values:
'none'or'mantel'(a Mantel test of the distances against the differences inx; seebdiv_stats()). The trendline is fitted to the pairwise distances for display only. Default:'mantel'- fit
How to fit the trendline.
'lm','log', or'gam'. Default:'gam'- at
Position(s) along
regrwhere group means or local slopes are evaluated. Default:NULL, which uses the median ofregrwithin eachsplit.bystratum. A vector gives one row per position, and p-values are adjusted across all of them. Ignored by tests that do not depend on a position (e.g. a global slope withfit = "lm").- level
The confidence level for calculating a confidence interval. Default:
0.95- p.adj
Method to use for multiple comparisons adjustment of p-values. Run
p.adjust.methodsfor a list of available options. The adjustment spans every p-value in the returned table (all metrics, strata, pairs, and positions). Default:"fdr"- transform
Transformation to apply to calculated values. Options are:
c("none", "rank", "log", "log1p", "sqrt")."rank"is useful for correcting for non-normal distributions before applying regression statistics. Default:"none"- ties
When
transform="rank", how to rank identical values. Options are:c("average", "first", "last", "random", "max", "min"). Seerank()for details. Default:"random"- seed
Random seed for permutations, rarefaction, random tie-breaking, and stochastic ordinations. Results are reproducible for a given seed, and the caller's random number generator state is left unchanged. Must be a non-negative integer. Default:
0- permutations
Number of random permutations to use. Default:
999- alt
Alternative hypothesis direction. Options are
'!='(two-sided; not equal tomu),'<'(less thanmu), or'>'(greater thanmu). Default:'!='- mu
Reference value to test against. Default:
0- strata
Dataset field with the blocking/subject variable. Permutation tests permute within strata; regression models include a random intercept per stratum. Default:
NULL- caption
Add a caption beneath the plot that states the input table (rarefied, unrarefied, or relative abundances) and the methods (metric parameters, statistical test, p-value adjustment). Default:
TRUE- check
Generate additional plots to aid in assessing data normality. Default:
FALSE- alpha
The alpha term to use in Generalized UniFrac. How much weight to give to relative abundances; a value between 0 and 1, inclusive. Setting
alpha=1is equivalent to Normalized UniFrac. Default:0.5- cpus
The number of CPUs to use. Set to
NULLto use all available, or to1to disable parallel processing. This also bounds R's linear algebra library (BLAS): whencpusis less than the number of threads that library is set to use, it runs on one thread until the call returns. See the Multithreading section of rbiom-package. Does not affect results, apart from rounding in the last digits of linear algebra (around 1e-15). Default:ecodive::n_cpus()(all available cores)- ...
Additional parameters to pass along to ggplot2 functions. Prefix a parameter name with a layer name to pass it to only that layer. For instance,
p.size = 2ensures only the points have their size set to2. Unprefixed parameters go to every layer whose function accepts them. An argument that no layer accepts is an error.
Value
A ggplot2 plot. The computed data points, ggplot2 command,
stats table, and stats table commands are available as $data,
$code, $stats, and $stats$code, respectively.
Aesthetics
The default colors are colorblind-friendly for up to 12 groups: Okabe and
Ito's palette ("okabe") for up to 8, and Paul Tol's ("tol") for 9-12.
Of the other palettes, "bright", "vibrant", "muted", "light", and
"carto" are also designed for color vision deficiencies. The available
categorical palette names are: "okabe", "carto", "r4",
"polychrome", "tol", "bright", "light",
"muted", "vibrant", "tableau", "classic",
"alphabet", "tableau20", "kelly", and "fishy".
Shapes can be given as per base R - numbers 0 through 17 for various shapes, or the decimal value of an ascii character, e.g. a-z = 65:90; A-Z = 97:122 to use letters instead of shapes on the plot. Character strings may used as well.
See also
Other beta_diversity:
bdiv_boxplot(),
bdiv_clusters(),
bdiv_heatmap(),
bdiv_ord_plot(),
bdiv_ord_table(),
bdiv_stats(),
bdiv_table(),
distmat_stats()
Other visualization:
adiv_boxplot(),
adiv_corrplot(),
bdiv_boxplot(),
bdiv_heatmap(),
bdiv_ord_plot(),
plot_heatmap(),
rare_corrplot(),
rare_multiplot(),
rare_stacked(),
stats_boxplot(),
stats_corrplot(),
taxa_boxplot(),
taxa_corrplot(),
taxa_forest(),
taxa_heatmap(),
taxa_stacked(),
taxa_upset(),
theme_rbiom()